Reg Dual Compliance Map
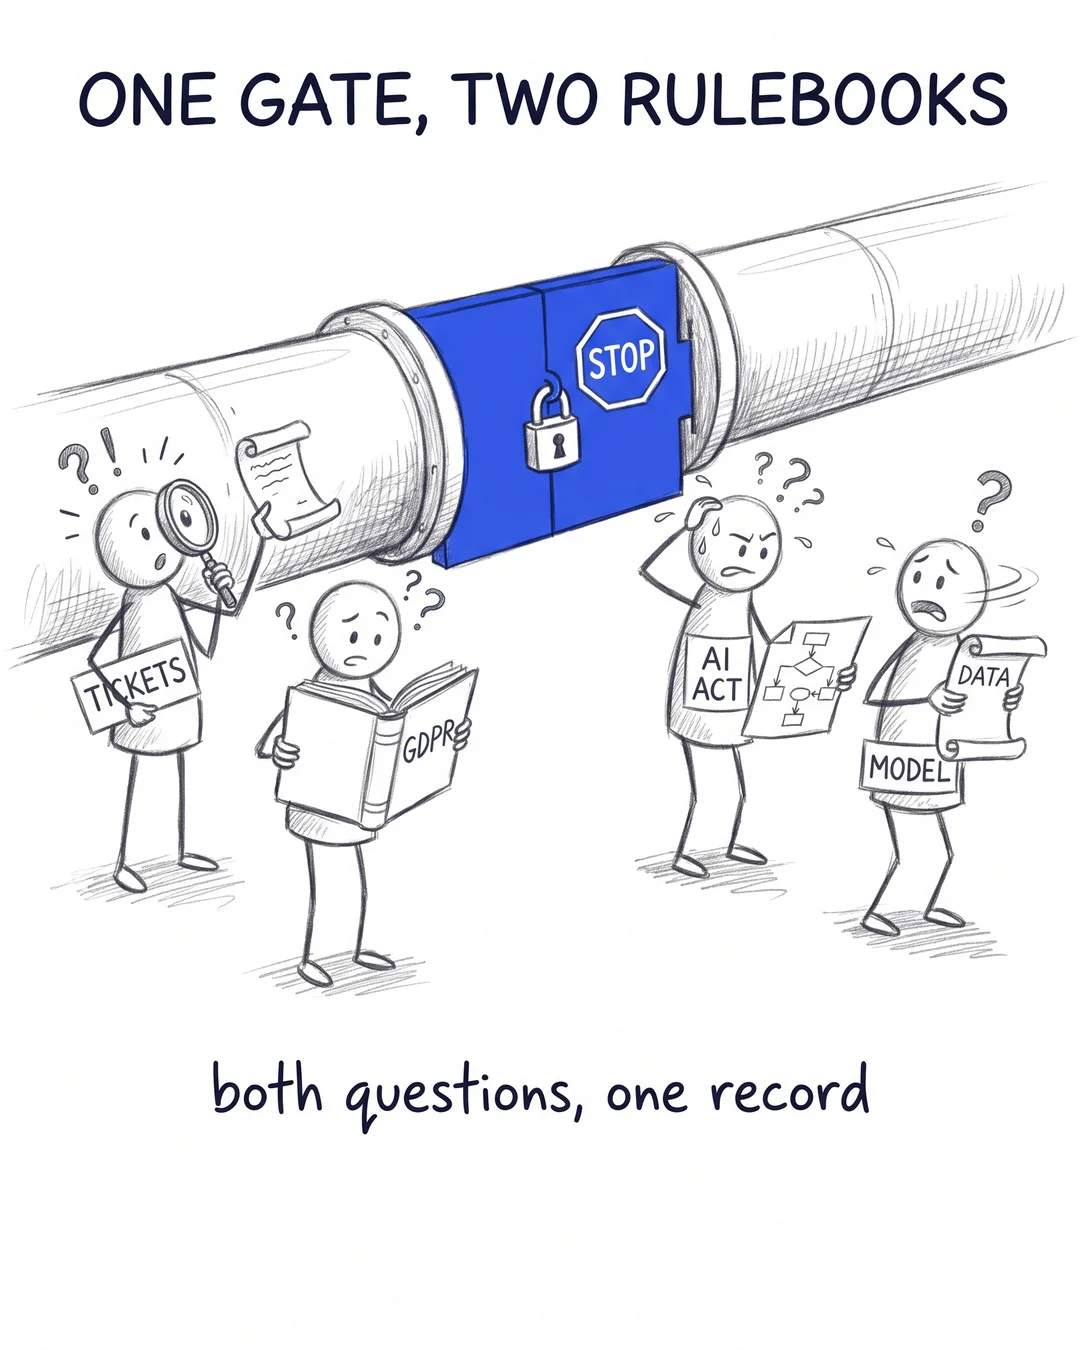
GDPR and the AI Act ask their questions at the same moment: when a dataset gets reused for a model.
Most teams I talk to run these as two tracks. Legal owns GDPR, and whoever builds the AI feature reads up on the AI Act. Both end up interviewing the same data engineer about the same tables.
The overlap sits in one place in the pipeline. Data collected for one reason, like support tickets or onboarding calls, gets picked up for something new, like grounding a chatbot or fine-tuning a classifier.
So I put a small gate there, a decision tree anyone can walk:
- Does the dataset hold personal data? Record the original purpose and check the new use against it, or strip what you don’t need.
- Does it feed a model? It needs a provenance record: source, date range, owner.
- Both? Nothing enters the training or retrieval set until both answers are written next to the dataset.
Legal review still happens. The reviewer reads one record, which in my experience makes the review quicker.
Who at your company decides whether an existing dataset can be reused for AI?
Fractional Data Architect helping startups and scaleups build data platforms that scale.
More about Thomas Nys →