BigQuery Scan Cost Surprises
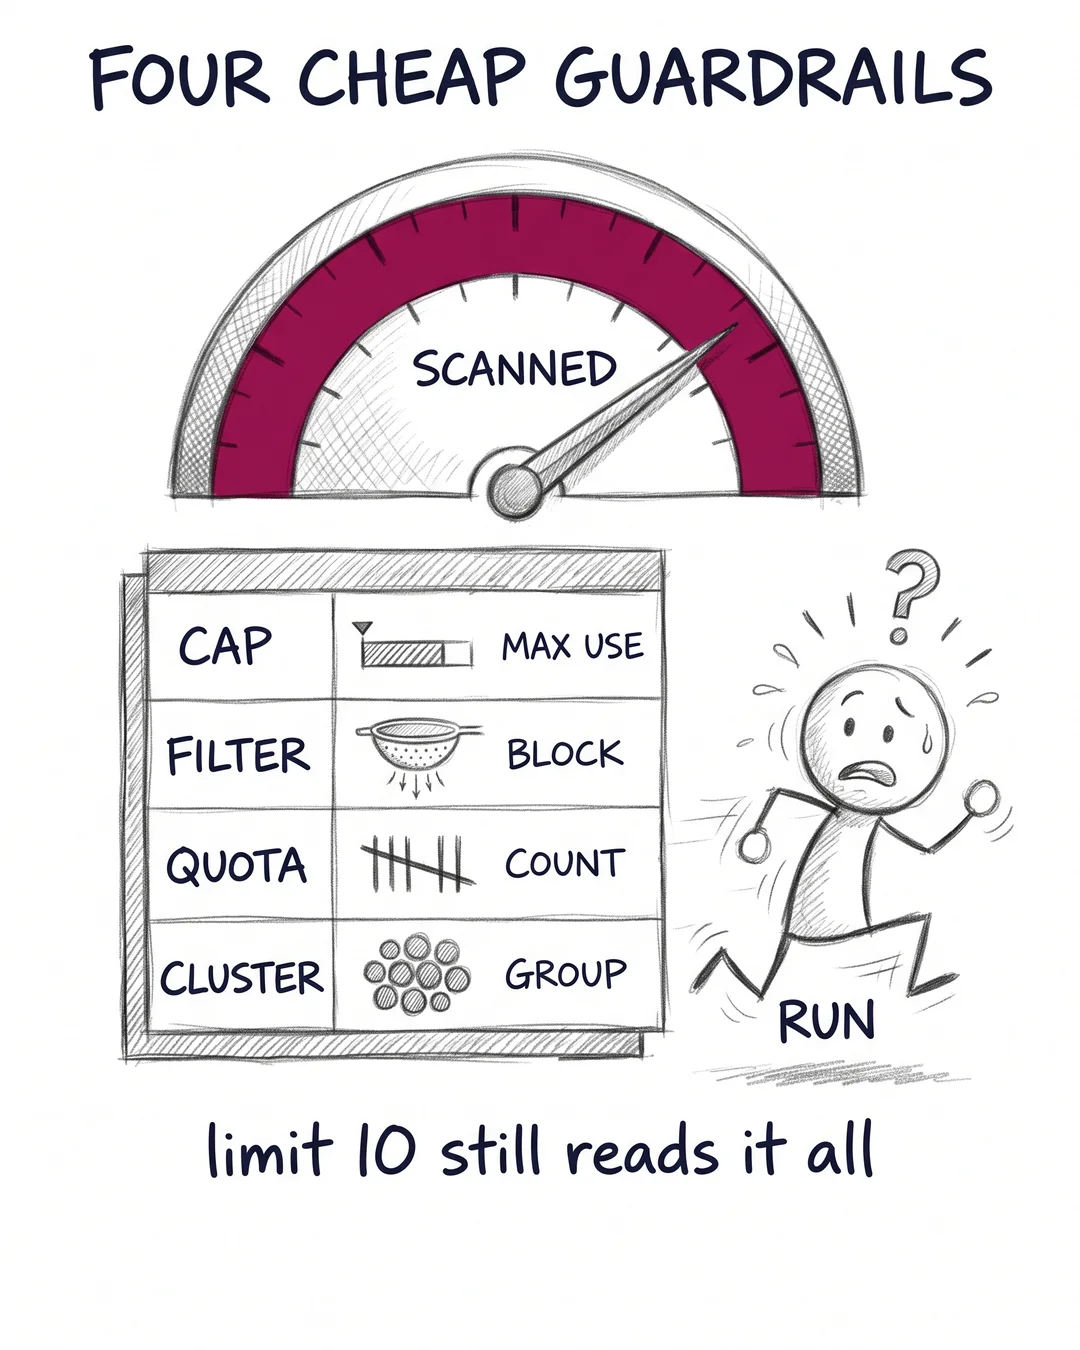
LIMIT 10 doesn’t reduce what BigQuery scans on an unclustered table. A lot of teams learn that from the invoice.
On-demand pricing bills per byte scanned. That suits scheduled pipelines, which read the same partitions every day. It’s rough on exploration, where someone runs SELECT * over three years of events to look at ten rows.
I usually add the guardrails in this order, least effort first:
- Maximum bytes billed, set in the tools analysts query from. A runaway query fails before it costs anything. Five minutes of config.
- Require a partition filter on the big tables. Queries without a date range get rejected. An hour, plus some grumbling.
- Custom daily quotas per user or project. The blunt one, and it caps the worst day.
- Clustering on the columns people filter by. More work, and it’s the only one of the four that makes honest queries cheaper too.
Before any of it, run one query on INFORMATION_SCHEMA.JOBS for the last 30 days and sort users by bytes billed. In my experience a few names account for most of it, and they’re rarely the pipelines.
If the top of that query surprises you, send me the line and I’ll say which guardrail I’d add first.
Fractional Data Architect helping startups and scaleups build data platforms that scale.
More about Thomas Nys →